Precise Error Conditions
1 LMU Munich, Germany · 2 Humboldt-Universität zu Berlin, Germany
This page belongs to the article Precise Error Conditions, which is under review at ACM TOSEM. It shows all our results, the plots of the paper, the log file of every benchmark run, and every query and answer of our case study on program repair.
Abstract
Maintaining software projects and repairing defects are time-consuming activities in software engineering. Most approaches for program repair focus on a single unsafe trace or failing test case, but deciding whether a patch truly fixes a defect in all aspects, identifying duplicate bug reports, or performing a root-cause analysis all require a precise description of the defect. We therefore introduce precise error conditions. They describe all and only the traces of a program that violate the given specification. Formally, they map program locations to predicates over the program state that must hold either always or at least once in all unsafe traces. We define precise error conditions and implement DescribErr, an open-source tool that synthesizes them and validates them formally. DescribErr instruments a candidate error condition into the program, reducing the check that it describes all and only unsafe traces to a verification task. An imprecise candidate yields a counterexample, i.e., a wrongfully included safe trace or a wrongfully excluded unsafe one, which DescribErr uses to refine the candidate, guaranteeing progress towards a precise error condition. On the SV-Benchmarks set, DescribErr finds precise error conditions for 2 076 of 7 192 considered defective tasks (28.9 %), spanning the unreach-call, no-overflow, and termination specifications and including real-world programs, like Linux device drivers and Juliet benchmarks. All our results, DescribErr, and the experimental setup are publicly available.
Approach
DescribErr searches for a precise error condition in a loop. A generator proposes a candidate. A validator then checks two things. Is the candidate sound, so does it describe only failing traces? And is it complete, so does it describe every failing trace? When a check fails, the verifier hands back a counterexample, and a refiner uses that counterexample to build a better candidate. A pruner drops the parts of a candidate that cannot help any more. A candidate that is both sound and complete is precise, and the loop stops.
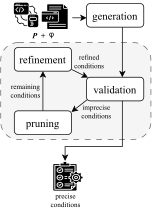
An error condition assigns a predicate to a program location. The predicate either holds every time the location is reached (□l p) or at least once (◇l p). We evaluate three ways to generate, prune, and refine candidates. The explicit analysis uses the values from a counterexample. The interval analysis uses ranges of single variables. The template analysis uses relations between several variables and fills them in with an SMT solver. All three run as a combination analysis, so one error condition can talk about several locations at once.
Tool and Reproduction Information
Our reproduction package on Zenodo
( )
has everything needed to run the experiments again, including the full log files.
DescribErr itself is open source and lives in our
 GIT repository.
Tool Versions
| Tool | What it does | Version |
|---|---|---|
| DescribErr | Synthesizes the precise error conditions | commit 7aeedbdf |
| TransVer | Turns no-overflow and termination tasks into reachability tasks | commit ecd35a59 |
| CPAchecker | Validates a candidate, the first tool we ask | 4.2.2, commit ad55ac6a |
| CBMC | Validates a candidate, good at finding bugs | 6.8.0 |
| UAutomizer | Validates a candidate, good at proving correctness | SV-COMP 2026 version (00d43373) |
| BenchExec | Runs the benchmarks reliably | 3.32 |
Benchmark Set
We use SV-Benchmarks in
the version of SV-COMP 2026
(branch svcomp26) and run DescribErr on every unsafe benchmark in the categories
unreach-call, no-overflow, and termination.
We leave out a task if the parser of DescribErr cannot read the program, or if TransVer cannot
turn it into a reachability task.
| Specification | Tasks with an error | Left out | Considered |
|---|---|---|---|
| unreach-call | 4 133 | 1 020 | 3 113 |
| no-overflow | 3 720 | 49 | 3 671 |
| termination | 974 | 566 | 408 |
| Total | 9 827 | 1 635 | 7 192 |
Machines and Limits
We run all benchmarks with BenchExec on machines with an Intel Xeon E3-1230 CPU (4 physical cores with 2 processing units each), 33 GB of RAM, and Ubuntu 24.04. Every run of DescribErr may use 28 GB of memory and 3 600 s of CPU time. To validate a candidate, we call three verifiers one after the other. CPAchecker gets 450 s of wall time, then CBMC gets 90 s, then UAutomizer gets 120 s. We synthesize error conditions for the last location with a nondeterministic value in every block of straight line code, so in code without loops, calls, or branches. Running the whole benchmark set once takes about two years of CPU time.
Full Results
The tables below hold all results of the paper, one table per specification. Each table shows the three analyses next to each other. Click a status cell to read the log of that run, and click a task name to open its task definition in SV-Benchmarks. The tabs above a table switch to the plots.
Note: All 26 481 log files that the tables link to are contained in this folder, so that every status cell opens the log of that run. Since the unzipped logfiles amount to 86 GiB of text, we omit the middle part of the content if the file is too big. The full data can be found in our reproduction package.
-
Results for unreach-call

4 133 tasks and 3 analyses. The same data as CSV.
-
Results for no-overflow
3 720 tasks and 3 analyses. The same data as CSV.
-
Results for termination
974 tasks and 3 analyses. The same data as CSV.
Research Questions
Five research questions guide our evaluation. RQ 1 to RQ 3 ask what DescribErr can synthesize and how long it needs for it. RQ 4 and RQ 5 ask what a precise error condition is good for once we have one.
RQ 1: How many precise error conditions does DescribErr find, and how many of them need the ◇ operator?
We consider 7 192 tasks. For 4 836 of them (67.2 %) DescribErr proves at least one candidate incomplete, which means that it finds a counterexample. For 2 076 of them (28.9 %) it finds a precise error condition. This is a lot, given that finding all failing inputs is much harder than finding one.
For 971 of these 2 076 tasks, no verifier ever found a single counterexample. That surprised us. Asking for a soundness proof and a completeness proof lets the verifier reason about all loop unrollings and branches at once, and that is sometimes easier than walking one concrete path to the error. Each of the three analyses also finds error conditions that the other two miss, so we need all of them.
| Specification | Considered | Cex. found | Precise EC found | ... by analysis | ... uniquely by analysis | |||||
|---|---|---|---|---|---|---|---|---|---|---|
| tasks | without cex. | Explicit | Interval | Template | Explicit | Interval | Template | |||
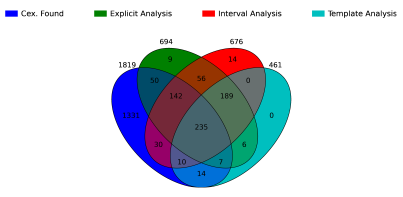
| unreach-call | 3 113 | 1 819 | 762 (24.5 %) | 274 | 694 | 676 | 461 | 59 | 44 | 14 |
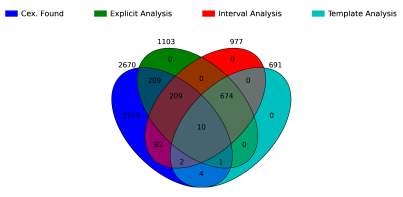
| no-overflow | 3 671 | 2 670 | 1 191 (32.4 %) | 674 | 1 103 | 977 | 691 | 209 | 82 | 4 |
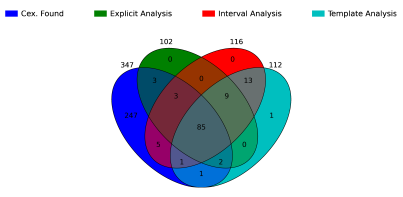
| termination | 408 | 347 | 123 (30.1 %) | 23 | 102 | 116 | 112 | 3 | 5 | 2 |
| Total | 7 192 | 4 836 (67.2 %) | 2 076 (28.9 %) | 971 | 1 899 | 1 769 | 1 264 | |||
Having both operators makes error conditions more expressive, but also harder to find. Of the 4 932 precise error conditions, 303 (6.1 %) need the ◇ operator. The termination tasks need it by far the most.
| Specification | Precise ECs found | Need ◇ |
|---|---|---|
| unreach-call | 1 831 | 87 (4.8 %) |
| no-overflow | 2 771 | 18 (0.6 %) |
| termination | 330 | 198 (60.0 %) |
| Total | 4 932 | 303 (6.1 %) |
-
Solved tasks per specification
unreach-call
no-overflow
termination
The tasks with at least one counterexample (Cex. Found) and the tasks where the explicit, the interval, or the template analysis found a precise error condition.
RQ 2: How much time does DescribErr need to find a precise error condition?
Most precise error conditions are found in less than 100 s of wall time. The first 10 s or so always go into parsing the program and into the transformation with TransVer. After that, almost all time goes into validation, because pruning and refinement are cheap. The template analysis is the exception, since it also spends time in the SMT solver that fills in the templates.
-
Time per analysis
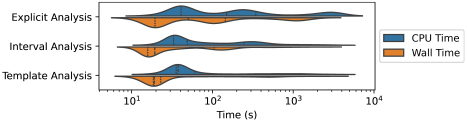
Density of the CPU time in blue and of the wall time in orange for each analysis, in seconds on a logarithmic x axis. The verifiers may run several analyses in parallel, which is why the orange curves sit further to the left.
-
Validation time against total time
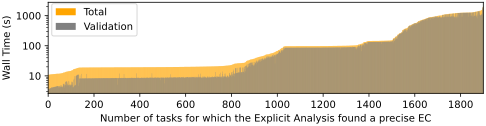
Explicit analysis
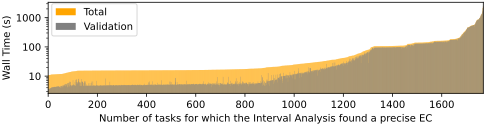
Interval analysis
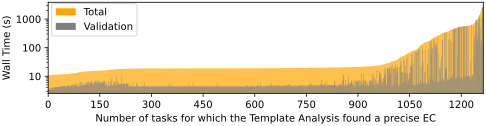
Template analysis
Wall time spent on validation in gray and total wall time in orange, in seconds, for all solved tasks sorted by wall time.
RQ 3: How close does DescribErr get on the tasks where it finds no precise error condition?
Even without a precise error condition, DescribErr reports partial results. A sound error condition describes only failing traces, so every input it allows really does trigger the failure. A complete error condition promises the other direction, that every trace it leaves out is safe.
The number of complete error conditions drops over the iterations, because the intervals get split at safe values and become small enough to be sound. The number of sound ones grows, because we keep every sound interval and then check whether their union is complete. The paper shows this for the interval analysis, one of our best analyses. We add the plots for the other two analyses here, and they behave the same way.
-
Sound and complete error conditions in the first 10 iterations
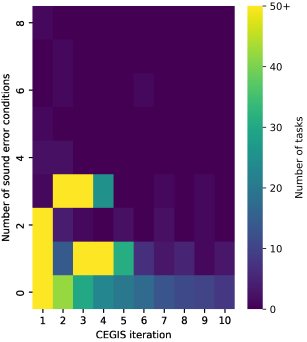
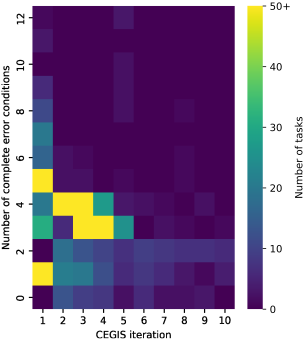
Interval analysis, sound on the left and complete on the right
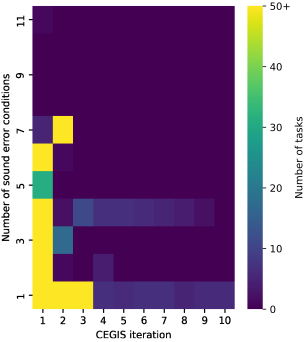
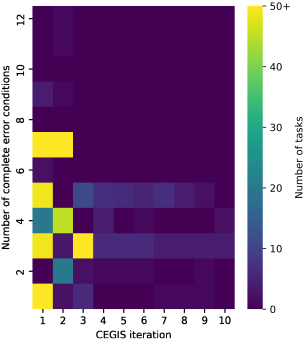
Explicit analysis, sound on the left and complete on the right
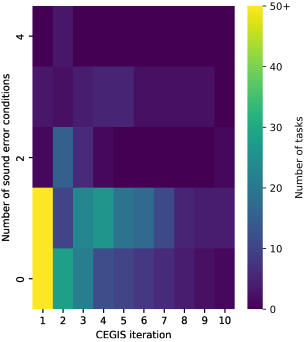
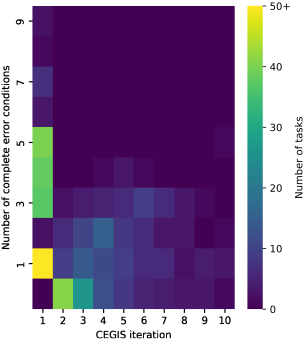
Template analysis, sound on the left and complete on the right
How many tasks (color intensity) have a given number of sound or complete error conditions (y axis) after a given number of iterations of the CEGIS loop (x axis).
RQ 4: What does a precise error condition tell us about a defect?
A precise error condition tells us where to look. It names the locations that matter and the variables that matter there. It says whether visiting a location once is already enough to fail (◇), which parts of the program are safe (□l false), and which assertions always fail (□l true). It also gives the values or the ranges of the relevant variables, and it shows whether the failure depends on one variable alone or on a relation between several of them.
The paper walks through the following error conditions as examples for these four groups. We moved their line numbers back to the original source code, so that they do not point into the code that DescribErr adds.
| Task | Ana. | Spec. | Error condition | What it says |
|---|---|---|---|---|
termination-crafted-lit/cstrncmp.c |
E | O | □l 28 (n = −231) | An edge case was not handled correctly |
Juliet_Test/CWE191...multiply_67_bad.i |
I | O | □l 1559 (data < −262) | |
float-newlib/double_req_bl_0870a.c |
E | R | □l 576 (x = −1.0) | |
coreutils-v9.5-units/getlimits...cover_proof.i |
E | R | ◇l 568 true | Once this location is reached, the error cannot be avoided |
combinations/pc_sfifo_1.cil-1+token_ring.01.cil-1.c |
I, T | R | ◇l 267 true | |
verifythis/tree_max_incorrect.c |
T | R | ◇l 51 true | |
ldv-regression/rule57_ebda_blast_2.i |
E, I | R | □l 66 false | The error happens when this location is not reached |
combinations/pc_sfifo_2.cil-2+token_ring.04.cil-1.c |
E | R | □l 552 false | |
nla-digbench-scaling/hard-ll_unwindbound1.c |
T | R | □l 33 (B − 1 < A) | Two variables have to relate in a certain way |
systemc/token_ring.01.cil-2.c |
T | O | □l 58 (E_M ≤ t1_st) | |
bitvector-loops/diamond_2-1.c |
T | R | □l 15 (y % 2 ≠ 0) |
The analysis that found the error condition (Ana.) is the explicit (E), the interval (I), or the template (T) analysis. The specification (Spec.) is unreach-call (R), no-overflow (O), or termination (T).
RQ 5: Do precise error conditions help an LLM repair a program?
We ran a small case study on 9 programs from SV-Benchmarks, three per specification. All three prompts are the same, except for what they say about the defect. The baseline prompt gives the program and the specification it violates. The test case prompt adds one failing input, which is what a repair tool based on tests would know. The guided prompt adds the precise error condition that DescribErr found.
The model is Qwen3-8B in the 4 bit
quantization Q4_K_M.
We run it on the CPU with llama.cpp on
4 threads, with a context of 16 384 tokens, an answer limit of 6 144 tokens, thinking
mode off, and the fixed seed 42, so the repairs come out the same every time.
The 27 answers take 55 min on an AMD Ryzen 7 with 16 cores.
CPAchecker then decides whether a repair satisfies the specification.
Two authors only answer what a verifier cannot answer, namely whether a verified repair is
plausible and which of several verified repairs is the better one.
They see the repairs blind and in a random order, and on all nine programs they came to the
same judgment.
| Task | Specification | Specification holds | Better and plausible repair | ||||||
|---|---|---|---|---|---|---|---|---|---|
| baseline | test case | guided | baseline | test case | guided | tie | none | ||
diamond_2-1 |
unreach-call |
no | no | yes | • | ||||
dijkstra-u_unwindbound5 |
unreach-call |
no | no | yes | • | ||||
stateful_check |
unreach-call |
no | no | no | • | ||||
CWE191...multiply_01_bad |
no-overflow |
? | yes | yes | • | ||||
ChenFlurMukhopadhyay-SAS2012-Ex2.10 |
no-overflow |
no | no | no | • | ||||
NonTermination1 |
no-overflow |
yes | ? | yes | • | ||||
AlternKonv |
termination |
no | no | yes | • | ||||
ComplInterv2 |
termination |
no | no | yes | • | ||||
dijkstra1-both-nt-2 |
termination |
? | ? | ? | • | ||||
| Total (9) | 1 | 1 | 6 | 0 | 0 | 5 | 1 | 3 | |
The specification columns say whether CPAchecker could prove the repair of the model against the original specification. A question mark means that the verdict was inconclusive, and none means that no repair was verified or plausible.
One failing input is no replacement for a precise error condition.
It tells the model where to look, but not what the repair has to achieve, so the model guesses
the criterion.
The error condition simply states it.
The table below shows what the two prompts actually revealed about each defect.
A failing input is a list of the values that the calls to the nondeterministic input functions
return, in the order of the calls.
The prompt does not state the error condition in the compact form shown here, it spells it out
in words, for example as
every time line 15 is reached,
.
y % 2 == 1 holds
| Task | Failing input in the test case prompt | Precise error condition in the guided prompt |
|---|---|---|
diamond_2-1 |
1 |
☐ y % 2 == 1 (line 15) |
dijkstra-u_unwindbound5 |
16 |
◇ 15 < n && n < 64 (line 23) |
stateful_check |
1, 0, 1, 1, 1, 1, 2, 1, 3 |
☐ the value that __VERIFIER_nondet_int() returns here is not 0 (line 59) |
ChenFlurMukhopadhyay-SAS2012-Ex2.10 |
1, -2147483648 |
(☐ 0 < x (line 25) ∧ ☐ y < -2147483647 (line 25)) |
CWE191_Integer_Underflow__int64_t_fscanf_multiply_01_bad |
-9223372036854775808 |
☐ data < -4611686018427387903 (line 40) |
NonTermination1 |
2147483522 |
◇ 1 < x (line 13) |
AlternKonv |
0 |
◇ (-2 < i) && (i < 2) (line 8) |
ComplInterv2 |
10 |
(☐ !(i == -3) (line 9) ∧ ☐ !(i == 2) (line 9) ∧ ☐ !(i == -1) (line 9) ∧ ☐ !(i == 1) (line 9) ∧ ☐ !(i == -2) (line 9) ∧ ☐ !(i == 3) (line 9) ∧ ☐ !(i == -4) (line 9) ∧ ☐ !(i == 4) (line 9) ∧ ☐ !(i == 0) (line 9)) |
dijkstra1-both-nt-2 |
1073977166 |
◇ h == q (line 31) |
Every query and every answer of this case study is on its own page, together with the verdict
that CPAchecker gave for each repair and the judgment of the two authors.
Browse the 27 repairs, or take the raw records
from fixes.json,
validation.json, and
labels.json.
The nine original programs and the 27 repaired ones are in this folder too, and the page links
to each of them.
The run sets are named after their analysis.
cex is the explicit analysis, interval is the interval analysis, and
template is the template analysis, which runs together with the explicit one.
Every analysis has two dates, one run for unreach-call and termination, and
one run for no-overflow.